SMART AI IMAGE DESCRIBER (PRODUCT)
AI vision model that transforms images into rich, detailed, human-readable descriptions
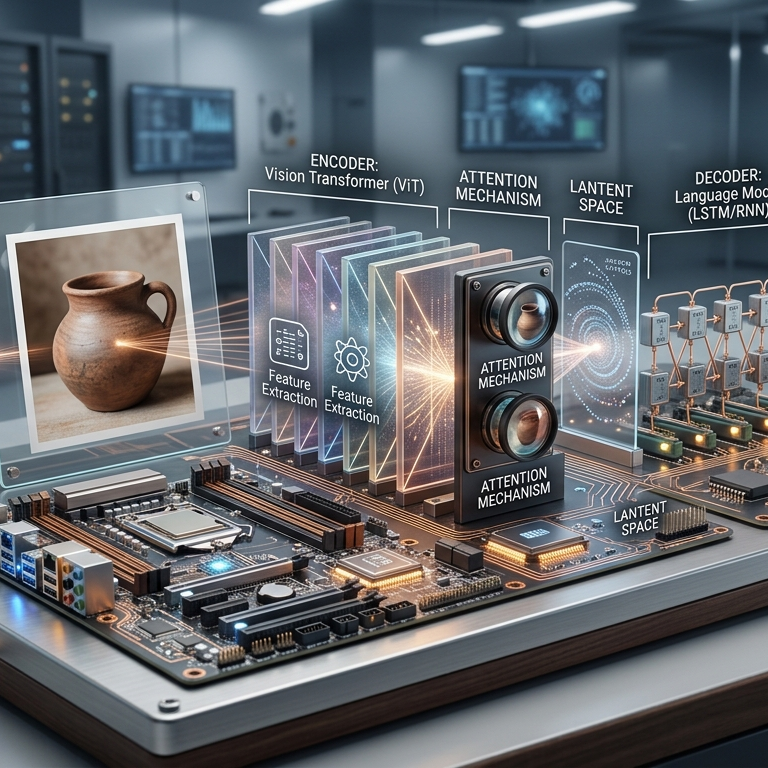
Description
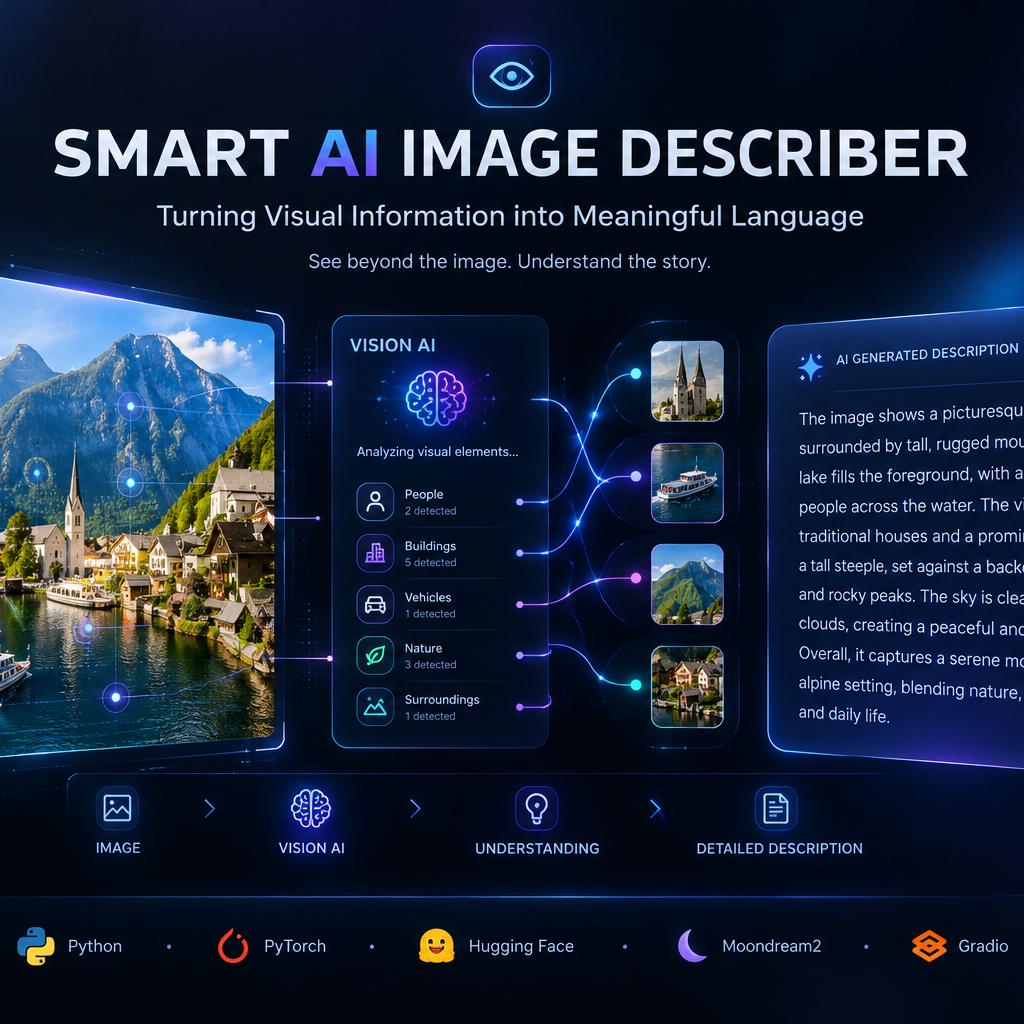
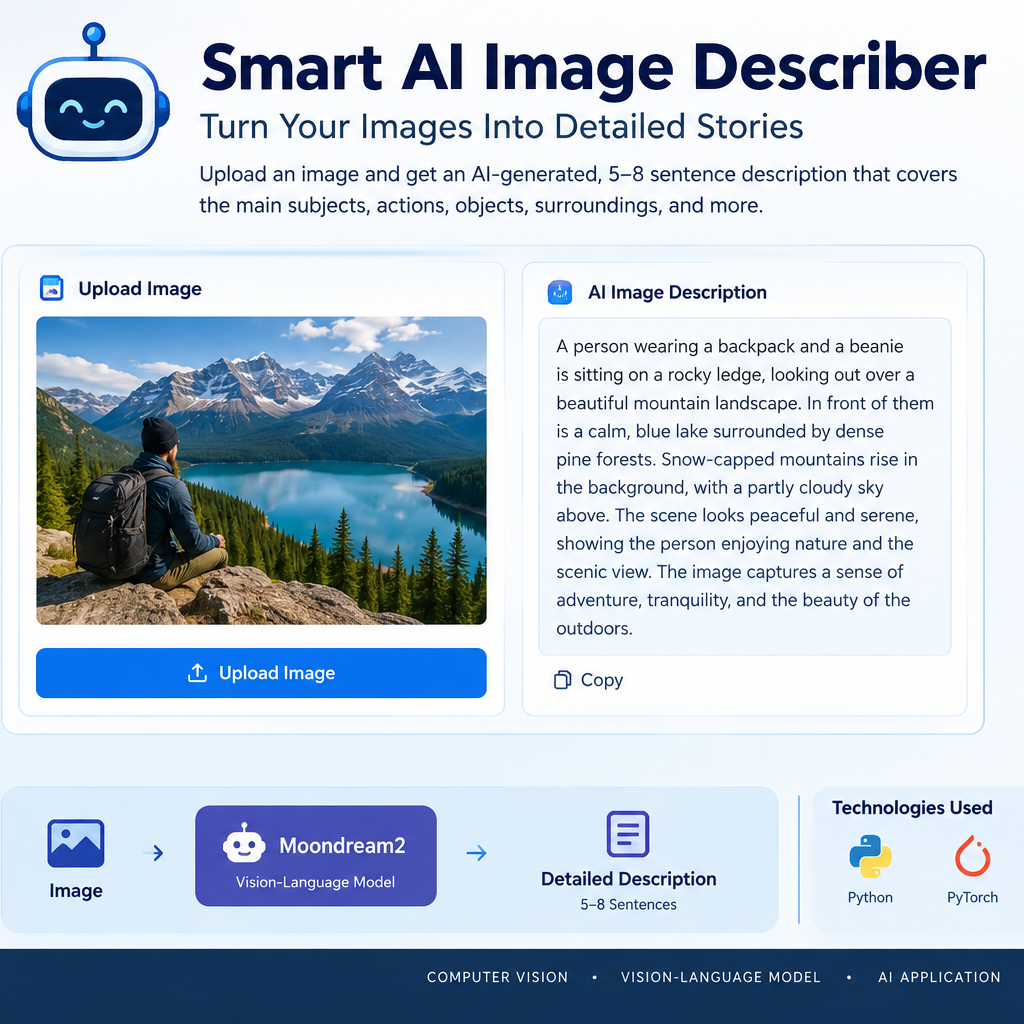
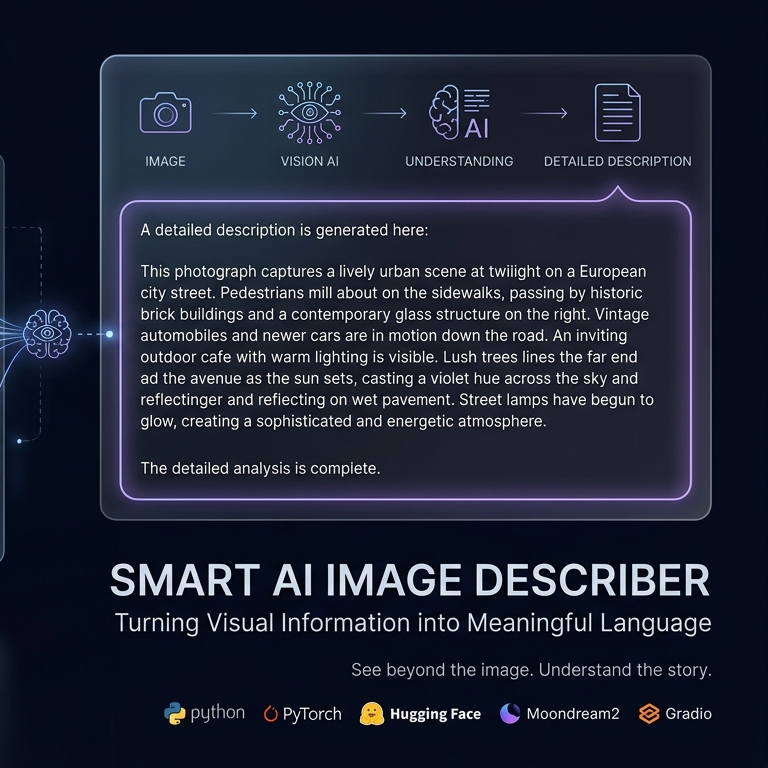
Smart AI Image Describer is a vision-language AI application designed to transform visual content into meaningful, detailed natural-language descriptions.
Built with Moondream2, PyTorch, Hugging Face Transformers, and Gradio, the system analyzes uploaded images and identifies visible subjects, objects, actions, surroundings, and contextual visual details. Instead of producing only short captions, it is designed to generate rich multi-sentence descriptions that provide users with a clearer understanding of an image.
The project demonstrates practical implementation of Computer Vision, Vision-Language Models (VLMs), Image-to-Text generation, AI inference, and interactive AI application development.
Key Features
- 🖼️ Image-to-text understanding
- 🤖 Vision-language AI
- 📝 Detailed multi-sentence descriptions
- 🔍 Visual object and scene understanding
- 🚀 Simple interactive Gradio interface
- ⚡ GPU-aware model inference
- 🔗 Hugging Face Transformers integration
Technologies
Python • PyTorch • Moondream2 • Hugging Face Transformers • Gradio • PIL
Live Deployment Sandbox
API Integration Guide
curl -X POST https://api.aimodelplace.com/api/v1/predict \
  -H "Authorization: Bearer YOUR_API_KEY" \
  -F "model_slug=smart-ai-image-describer" \
  -F "file=@/path/to/your/file"
Successful response format (JSON):
{
    "balance_remaining": 630,
    "latencyMs": 69,
    "predictions": [
        {
            "confidence": 0.9464548230171204,
            "label": "Sample Label"
        }
    ],
    "recognized_object": "Sample Label",
    "success": true,
    "tokens_consumed": 10
}
For more detailed parameters and SDK examples, visit our Full API Documentation.
Post Your Comments
Login to comment